/* Vid-To-Text */
/**
*
*/
Description
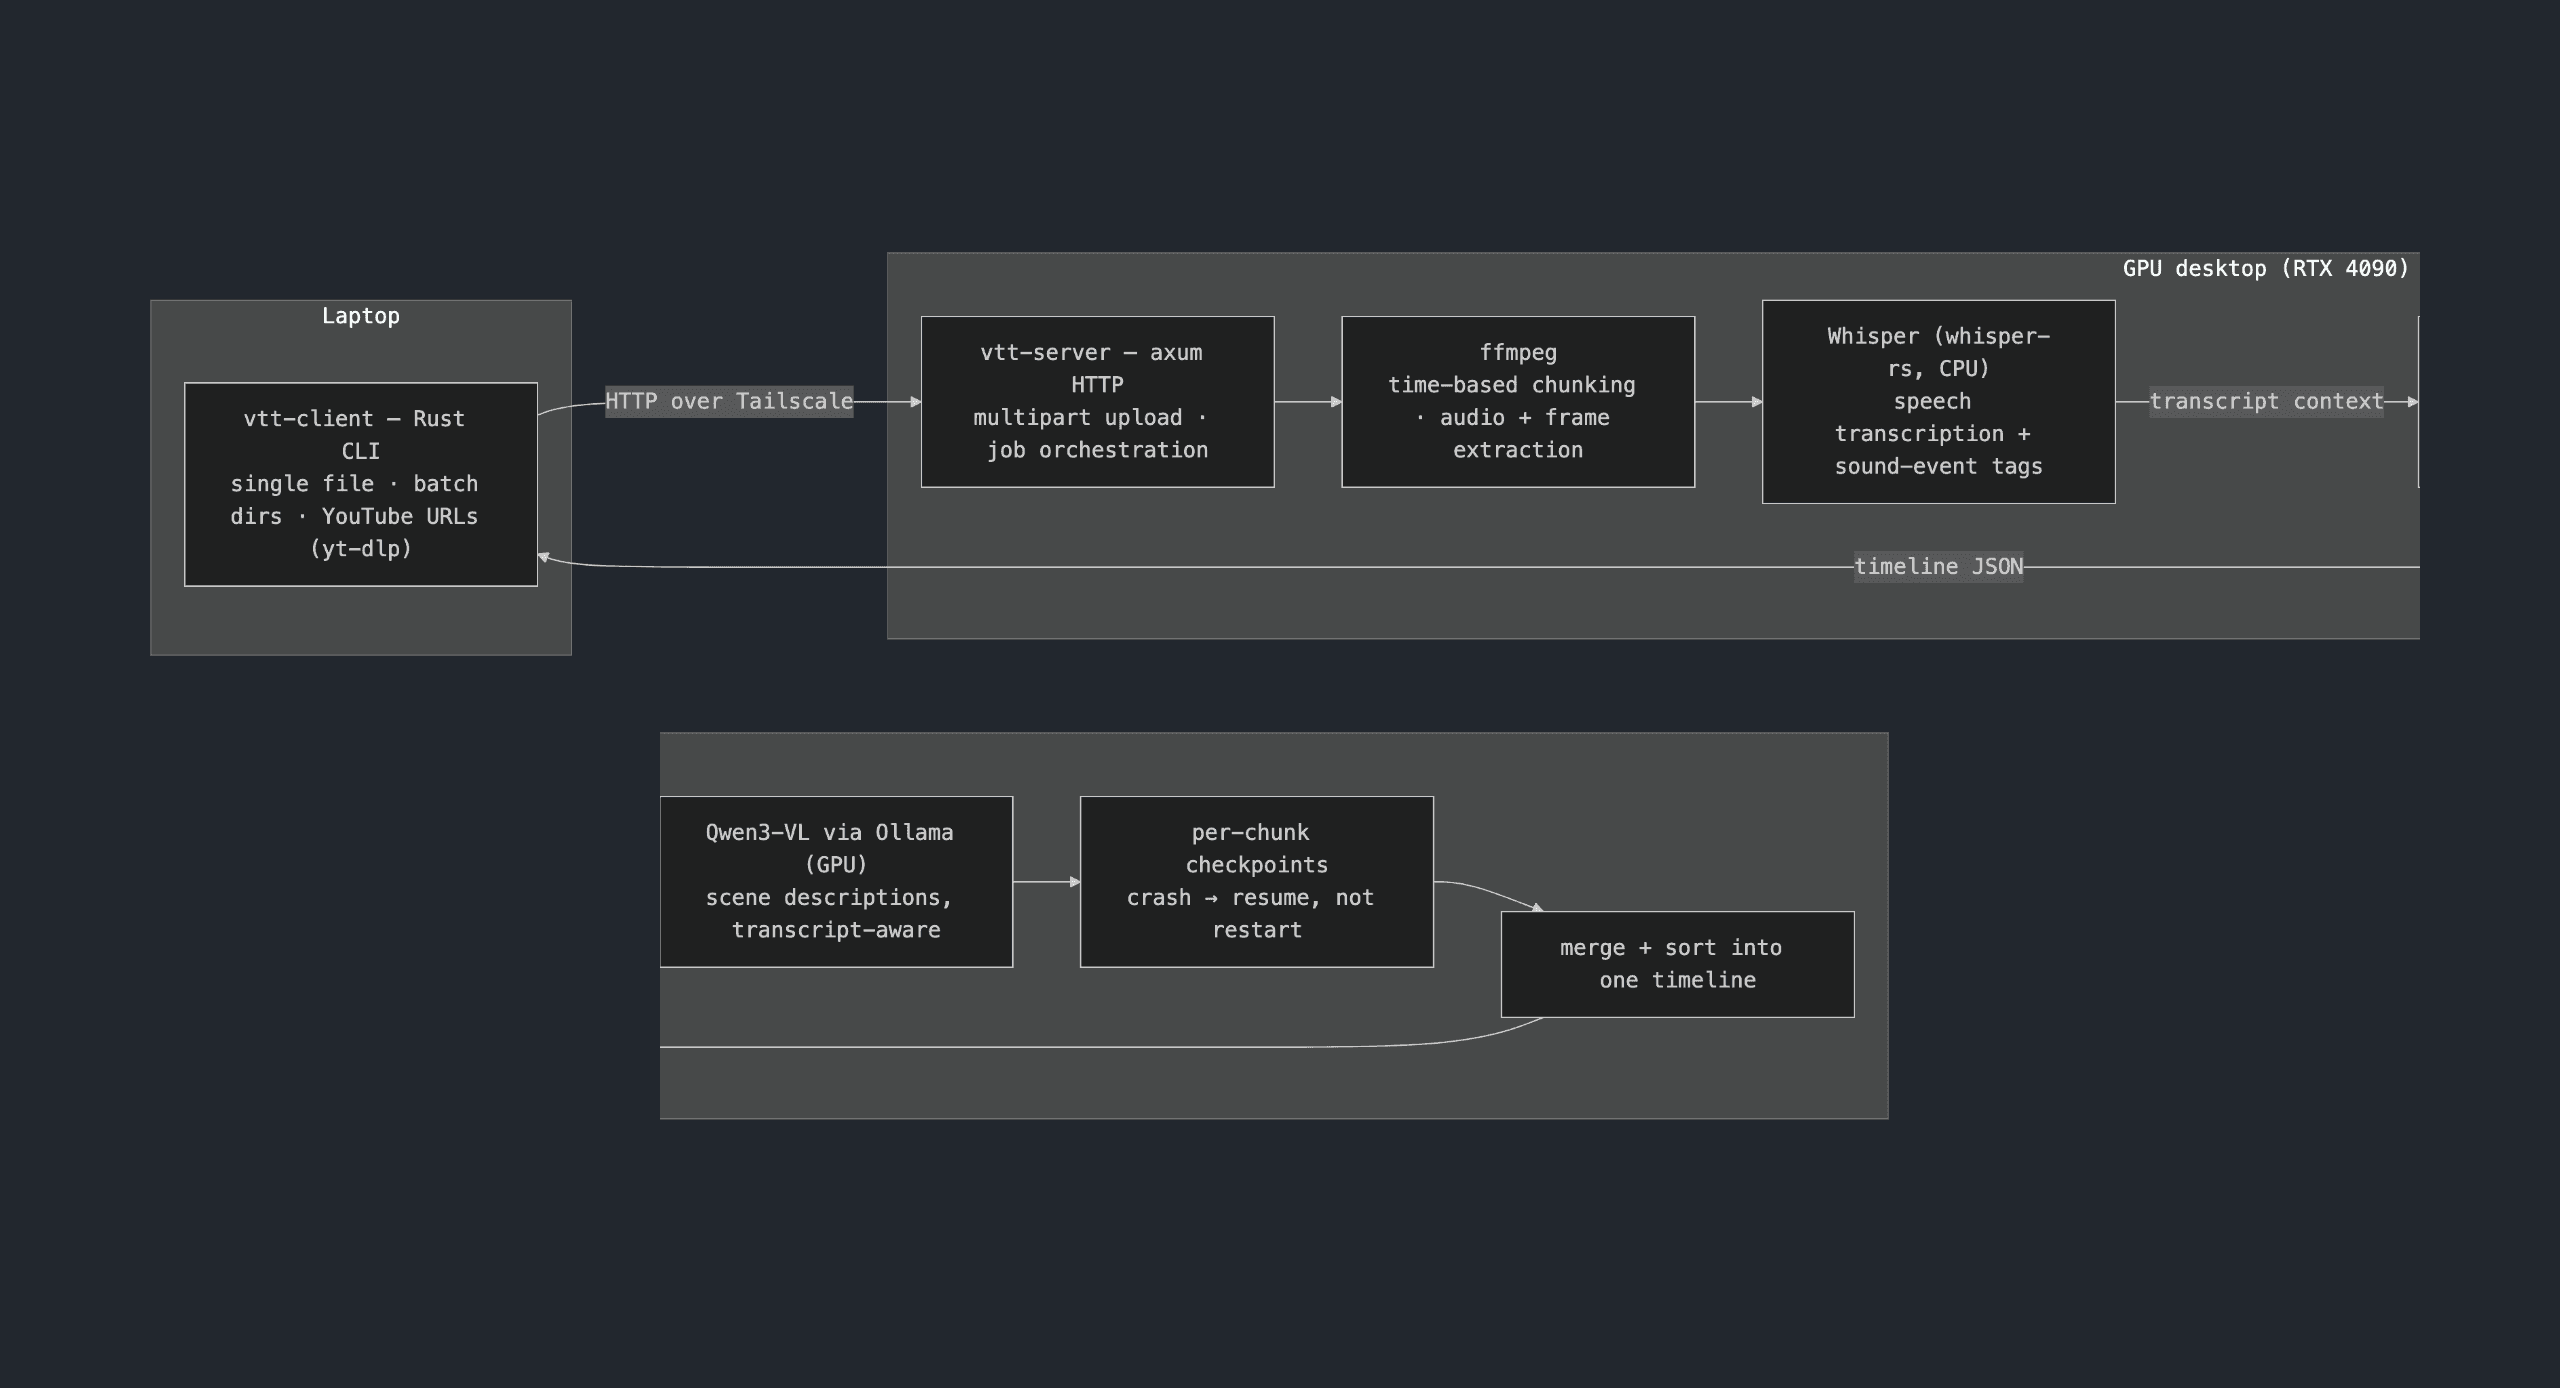
Turns video into a timestamped speech/visual/sound timeline using local models (Whisper on CPU, Qwen3-VL via Ollama on GPU), with ffmpeg chunking, transcript-aware vision prompting, and crash-resumable jobs. A Rust client/server pair; nothing leaves my machines except an optional formatting step.